I develop hardware-aware algorithms for low-precision LLM training and inference, aiming to improve model quality under compute and memory constraints.
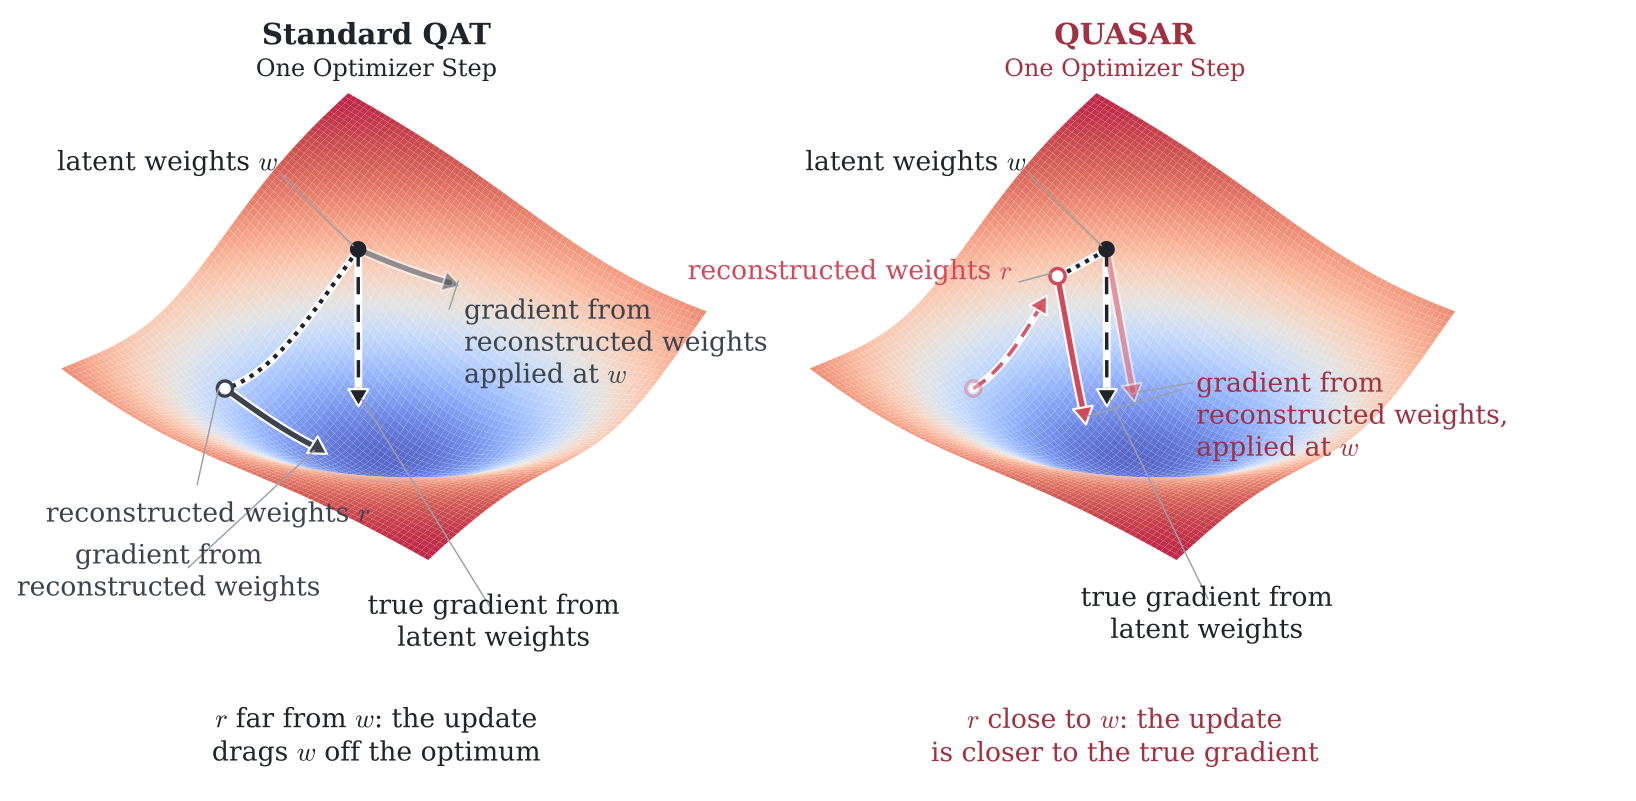
QUASAR treats quantization-aware training as a weight reconstruction problem, continuously fitting a loss-aware quantized representation as the latent full-precision weights evolve. Its analysis connects weight reconstruction quality to the optimization dynamics and final quantized-model loss.
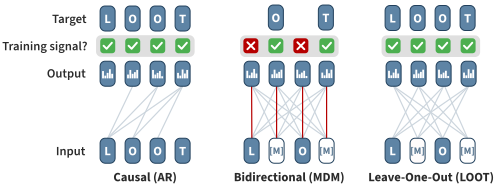
LOOT predicts each token from the rest of the sequence, allowing masked diffusion language models to learn from every token and self-correct during generation.